
LLM-First SEO: How to Rank in Modern Search and AI Retrieval Engines
Short answer
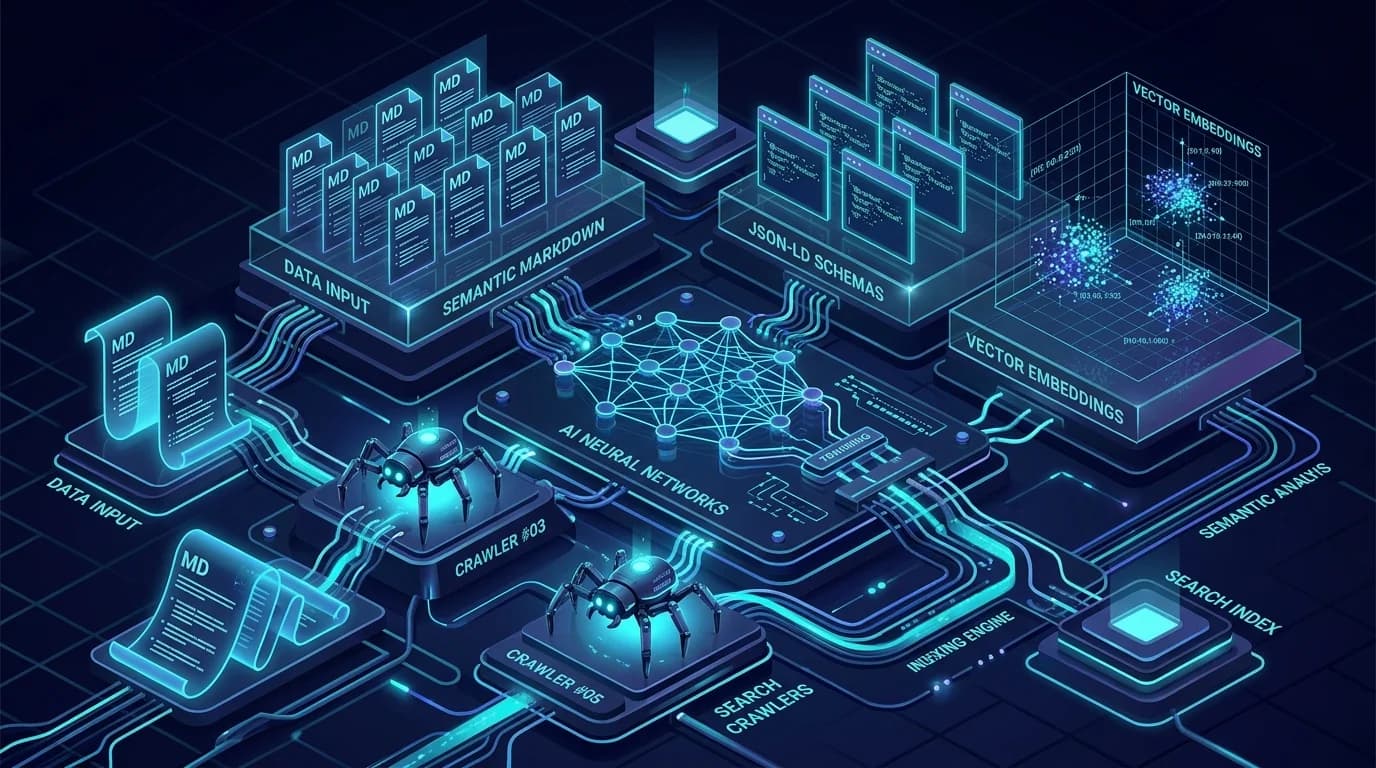
LLM-first SEO is the practice of structuring digital content for dual discovery: search crawler indexing and large language model ingestion. Unlike traditional keyword-targeted ranking, LLM SEO emphasizes factual density, schema markup, semantic markdown hierarchies, and markdown manifests like llms.txt. This ensures artificial intelligence engines and crawlers accurately retrieve, comprehend, and cite your domain.
The Evolution from Crawler Indexing to LLM Retrieval
For over two decades, search engine optimization focused exclusively on how traditional search spiders parse HTML documents. Crawlers like Googlebot and Bingbot evaluated keyword distribution, backlink PageRank, and document metadata. However, the emergence of AI answer systems like Perplexity, ChatGPT Search, and Claude has permanently altered web discovery.
Modern search systems do not merely match query strings against index tokens; they ingest content into vector retrieval databases and RAG (Retrieval-Augmented Generation) pipelines. An effective digital footprint must now be understandable to both token-based search crawlers and semantic embedding models.
Core Pillars of LLM-First SEO Architecture
To succeed in the AI retrieval era, engineering teams must implement technical standards that prioritize structured data clarity over promotional marketing prose:
- Standardized /llms.txt manifests: Clean, curated Markdown route summaries that provide AI agents with concise contextual maps of your entire product and service catalogue.
- Semantic HTML and Markdown parity: Providing plain-text representations of complex pages so retrieval agents consume structured facts without executing heavy JavaScript bundles.
- Rich Schema JSON-LD hierarchies: Nested schemas using SoftwareApplication, FAQPage, BreadcrumbList, and Person nodes that explicitly define relationships and authorship.
- Dense statistical data: Replacing vague adjectives with verifiable metrics, pricing tiers, specifications, and technical benchmarks that LLMs extract into synthetic summaries.
Comparison: Traditional SEO vs LLM-First SEO
| Evaluation Metric | Traditional SEO | LLM-First SEO |
|---|---|---|
| Primary Target | Search engine indexers (Google, Bing) | Search bots, RAG pipelines, and LLM answer engines |
| Content Focus | Keyword density and search intent volume | Factual accuracy, entity depth, and extractable data |
| Technical Priority | Fast page speed, mobile responsiveness, XML sitemaps | SSR rendering parity, /llms.txt, JSON-LD, clean Markdown |
| Success Metric | SERP ranking positions and organic clicks | Direct answer citations, brand inclusion, and referral traffic |
Implementing Machine-Readable Manifests with llms.txt
The /llms.txt specification serves as a dedicated navigation manifest for AI agents. By curating a structured summary of core offerings, APIs, and product documentation, companies eliminate the crawling noise that causes hallucination. For high-volume technical platforms, maintaining both a concise /llms.txt and an exhaustive /llms-full.txt ensures that search models retrieve accurate specifications directly.
In production workflows, generating these files directly from verified codebase data ensures that your documentation remains synchronized with shipping software versions. When new features or architectural changes deploy, automated prebuild hooks update both the human-facing documentation and the machine-readable manifest.
Frequently Asked Questions About LLM-First SEO
Frequently Asked Questions
Does LLM-first SEO replace traditional search engine optimization?
No. LLM-first SEO builds on solid technical SEO fundamentals. Traditional indexing remains essential because search engines provide the primary index from which AI models retrieve grounding sources.
Why is an llms.txt file necessary if a website already has a sitemap.xml?
XML sitemaps provide URLs and timestamps for web spiders. An llms.txt file provides clean, markdown-formatted summaries and documentation structure designed for LLM context windows and token efficiency.
How can web developers test how AI engines perceive their pages?
Developers can inspect raw curl outputs against headless browser rendering to ensure content parity, and audit their domain using automated SEO diagnostic tools that verify citability and schema completeness.
What is the role of structured data in AI search retrieval?
Structured schema markup provides explicit semantic labels that remove ambiguity from raw HTML text, allowing embedding models to identify entities, licensing parameters, and author qualifications.
Need Setup or Custom Coding?
Get in touch to rebrand or customize our ready-made products, or discuss custom development services. All quotes are customized and private.
Related Articles
Multi-Location Inventory Management Software: Real-Time Stock Sync & Batch Tracking
Discover how self-hosted multi-location inventory management software tracks stock balances, batch expiry dates, and automated purchase orders across warehouse networks.
Answer Engine Optimization (AEO): Formatting Content for Conversational Search
Discover Answer Engine Optimization (AEO) strategies to position your business as the cited answer in ChatGPT, Perplexity, Claude, and Google AI Overviews.