
RAG Chatbot Development for Business Data: A Practical Guide
Short answer
A generic AI chatbot knows the internet but not your refund policy, product specs or service areas, so it guesses. Retrieval-Augmented Generation fixes that: your documents are chunked and indexed, the relevant passages are retrieved for each question, and the model answers only from what it retrieved.
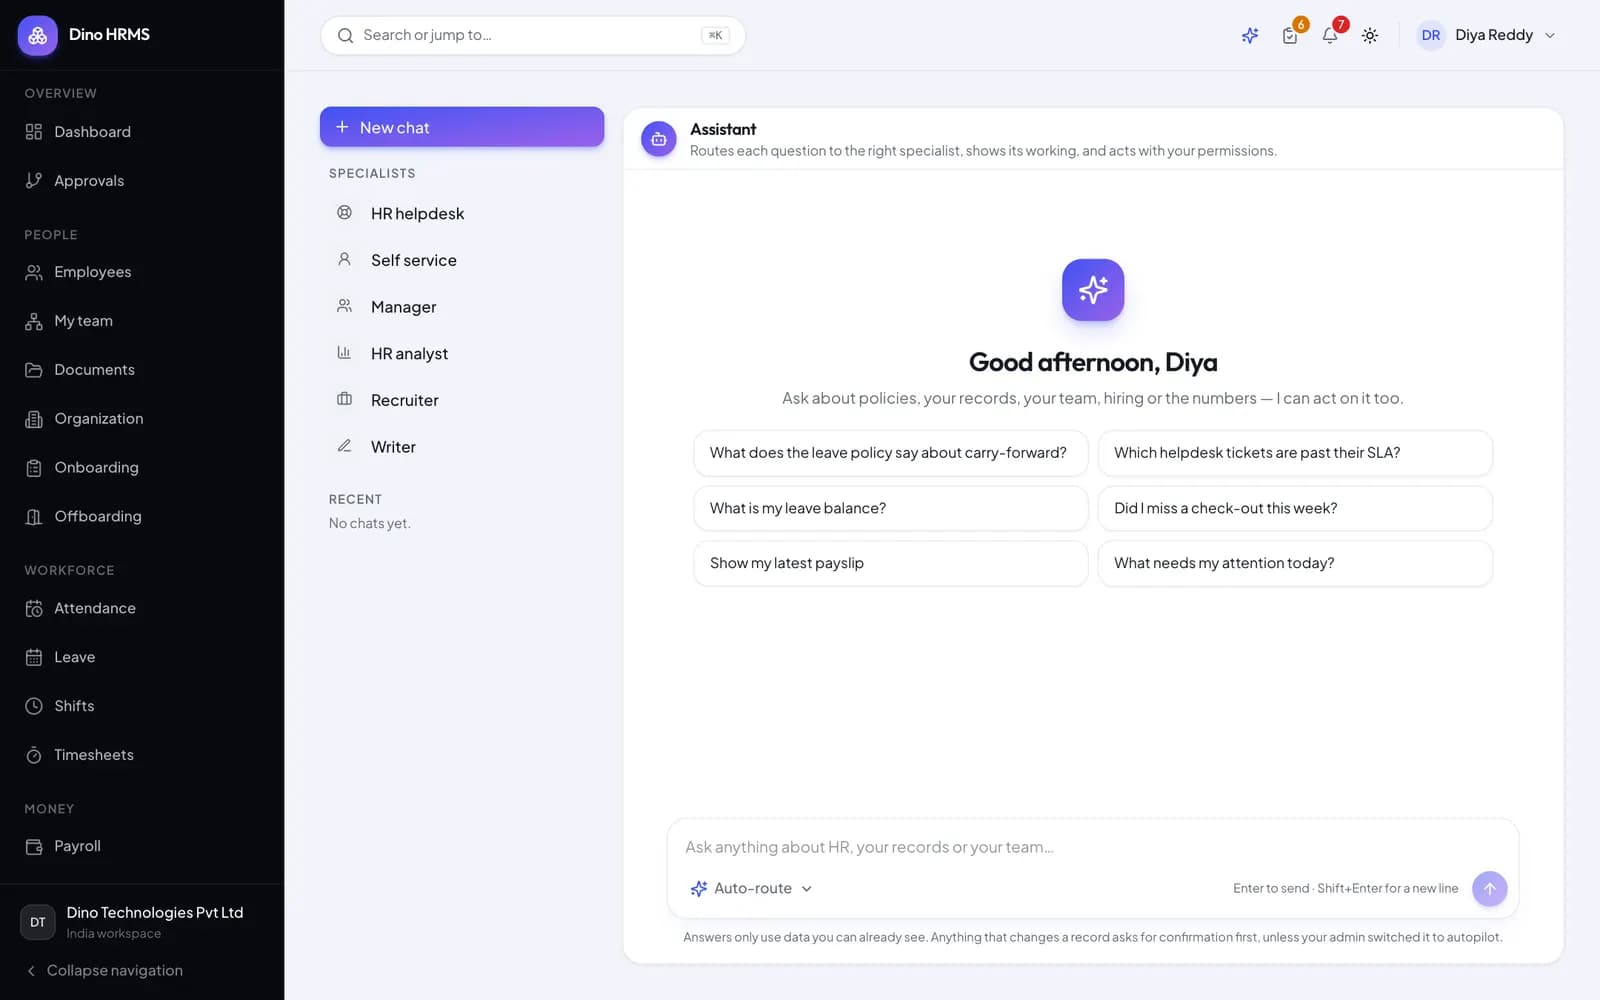
Software discussed: Dino Business OS · Try the live demo
A generic AI chatbot knows the internet but not your business. Ask it about your refund policy, your product specs, or your service areas and it guesses. Retrieval-Augmented Generation (RAG) fixes this: the bot retrieves relevant passages from your own documents first, then answers only from what it found.
How a RAG Pipeline Works
- Ingest: your documents (PDFs, FAQs, product data, policies) are split into chunks.
- Embed: each chunk becomes a vector — a numerical fingerprint of its meaning.
- Store: vectors live in a vector database such as Qdrant or pgvector.
- Retrieve: a user question is embedded and matched against the closest chunks.
- Generate: the language model writes an answer grounded in those retrieved chunks — with sources.
Why RAG Beats Fine-Tuning for Business Data
Fine-tuning bakes knowledge into a model — expensive to update and impossible to audit. RAG keeps knowledge in a database you control: update a document, re-index, done. Answers can cite their source chunks, and confidence thresholds let the bot say "I don't know" instead of inventing policy that doesn't exist.
Where RAG Chatbots Pay Off
- Customer support: instant answers from your real policies and manuals.
- Ecommerce: product questions answered from catalog data and spec sheets.
- Real estate: buyers query listings and brochures conversationally.
- Internal knowledge: staff search SOPs, HR policies, and technical docs.
- Lead qualification: the bot answers pre-sales questions and captures contact details.
Controlling Hallucination
The practical safeguards: restrict answers to retrieved context, set similarity thresholds below which the bot declines to answer, show source citations, and log every question-answer pair for review. A RAG bot configured this way is substantially more reliable than an ungrounded LLM — this is how TechDino builds RAG chatbots for client deployments.
What a Deployment Involves
- Document pipeline: parsers for your formats (PDF, CSV, HTML, database rows).
- Vector store on your infrastructure — your data never trains third-party models.
- Chat widget embedded on your website or app, matching your brand.
- Admin view: conversation logs, unanswered-question reports, document re-indexing.
- Ongoing tuning: chunking strategy and thresholds adjusted from real usage.
Read about our RAG chatbot development service, see how AI agents help small businesses, or discuss your use case with us.
What Drives RAG Chatbot Cost
RAG projects are priced on the data work, not the model. The chat interface is the small part; getting your content into a state where retrieval returns the right passage is the project:
| Factor | Why it moves the number |
|---|---|
| Content volume | More documents means more chunking, indexing and evaluation work |
| Content format | Clean text is cheap; scanned PDFs, spreadsheets and slide decks need extraction first |
| Content quality | Contradictory or outdated documents must be reconciled — retrieval cannot fix a wrong source |
| Update frequency | A one-time index is far simpler than a pipeline that re-ingests on every change |
| Number of sources | Each system — site, docs, CRM, ticketing — is its own connector |
| Access control | Answers that must respect per-user permissions require filtering at retrieval time |
| Accuracy bar | Internal tools tolerate errors; customer-facing answers need an evaluation set and review cycles |
| Channels | Web widget, WhatsApp and Slack are separate integrations |
Running Costs
- Model API usage, which scales with conversation volume and how much context each answer retrieves.
- Vector storage and search, scaling with the size of your indexed corpus.
- Re-ingestion whenever source documents change.
- Ongoing evaluation — answer quality drifts as your content changes, and nobody notices without checks.
The cheapest way to reduce all of it is to narrow the scope: index the twenty documents that answer eighty percent of real questions rather than the entire archive. If the goal is to take actions rather than answer questions, you need something different — see AI agent vs chatbot.
For a production example of these costs in a shipped product, Dino Business OS runs a self-hosted knowledge base with Qdrant and per-user permission scoping, with token usage tracked in its own dashboard.
Frequently Asked Questions
Does my data leave my control?
Document storage and vector search run on infrastructure you control. Model calls go to your chosen AI provider under your API keys; providers' API terms govern that traffic, and we configure providers that don't train on API data.
How long does a RAG chatbot project take?
A focused deployment — one knowledge domain, website widget, admin logs — is typically a few weeks including document pipeline and tuning. Scope grows with formats and integrations.
What does it cost to run?
Ongoing costs are your AI provider's API usage (per query) plus hosting for the vector database — both usage-based and billed by those providers directly.
The software in this article
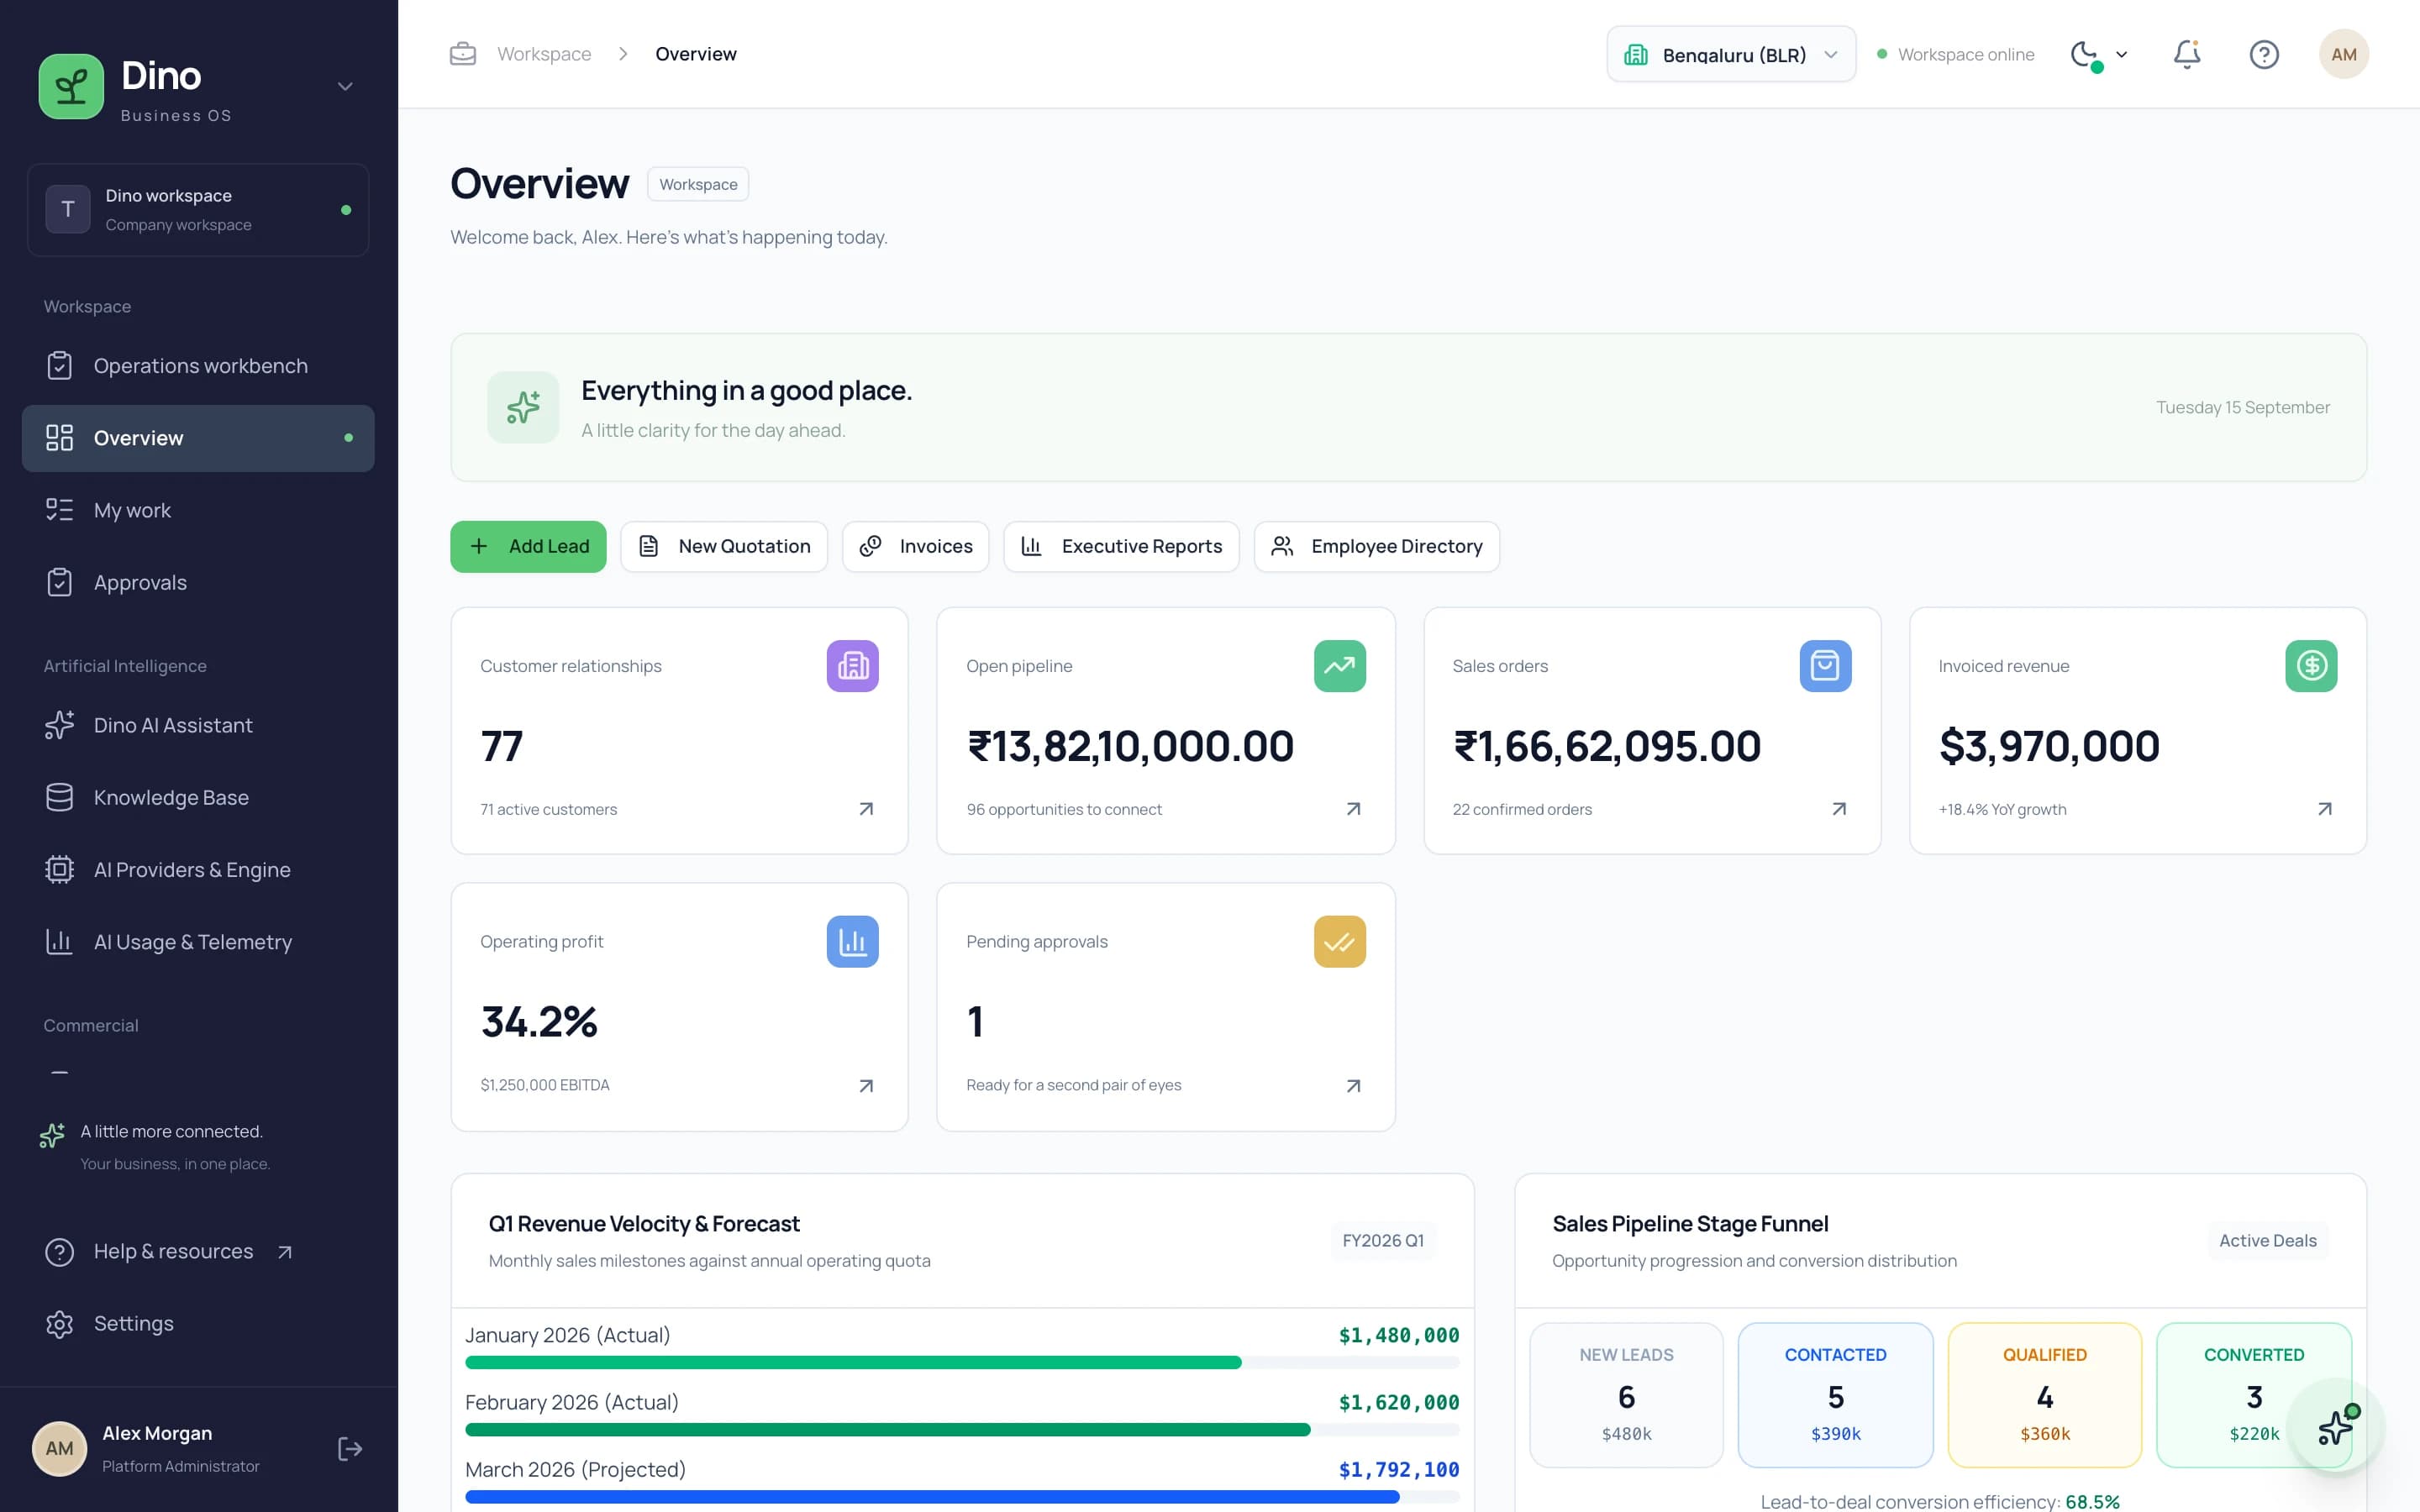
Dino Business OS
Dino Business OS is AI-powered business operations software that connects CRM, sales, procurement, inventory, projects, HR, payroll, service, assets, documents and finance in one permission-controlled workspace with a built-in LangGraph multi-agent AI assistant.
Explore Next
- Learn about our RAG chatbot development
Want Dino Business OS Under Your Brand?
Rebrand Dino Business OS with your logo and domain, or have it customized for your workflow. All quotes are customized and private.
Related Articles
Deploying Enterprise RAG on Private Business Documents: Architecture, Vector Databases, and Guardrails
A technical blueprint for deploying enterprise Retrieval-Augmented Generation on private internal documents with pgvector, hybrid search, and hallucination guardrails.
Claude Code Single Folder Setup: Folder Structure and Prompting Guide for Websites and Web Apps
Learn how to organize a Claude Code project folder with README, CLAUDE.md, docs, prompts, frontend, backend, testing, deployment files, and reusable prompts to build websites and web apps faster.